Edge Database Hosting: Check Read Locality, Writes and Freshness
Moving a database read closer to an application can reduce one network trip. It does not prove that every request becomes faster, that writes are local or that the application no longer needs a primary region.
The earlier article’s universal latency targets, instant-retrieval claims and automatic compliance promises have been removed. “Edge database” is a broad description; evaluate the actual data placement, routing and consistency model.
Trace the complete request
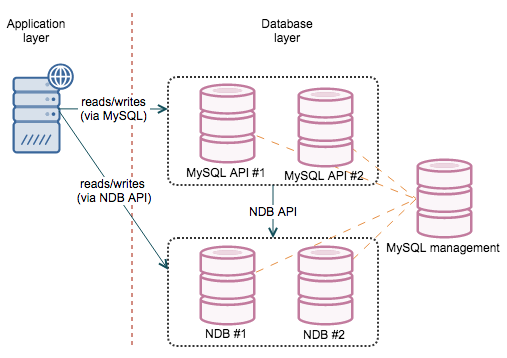
Draw the path from visitor to application, database and external services. Identify where the query runs and where its data lives. A nearby application process may still call a distant database, and a nearby database may not help an application waiting on another remote dependency.
Use representative queries and user locations to measure the complete response. Separate cached reads, uncached reads and writes. Do not infer database performance or SEO results from a network-point count.
Distinguish read replicas from distributed writes
Cloudflare’s D1 read-replication documentation provides a concrete example. Read replicas are asynchronous copies; writes still go to the primary. Using the Sessions API is required for the documented replica behaviour and provides sequential consistency within a session.
That example is not a universal specification for all edge services. Check the chosen product’s routing, API requirements and failure behaviour. A read-oriented design is different from accepting coordinated writes in multiple locations.
Define what fresh enough means
A stale catalogue description may be tolerable while an old account balance or revoked permission may not be. State the freshness and transaction requirements for each operation before selecting a consistency model.
Test a write followed by a read from another location, changed permissions and conflicting updates. Determine whether the service waits, routes to an authoritative copy, returns older data or fails the request.
Distributed systems do not all make the same choice. Spanner’s consistency documentation describes a different model. Product guarantees and deployment choices matter more than a blanket claim that all edge databases are eventually consistent.
Check the cost and data footprint
Include copies, request or compute charges, writes, synchronisation, transfer and monitoring. Record how deletion, retention and restoration affect replicas and indexes. A performance benefit can still create additional operating work.
Map primary data, replicas, backups, logs and support access. Region controls are useful features to verify, but they do not by themselves establish complete compliance. Review the actual processing and access arrangement.
Pilot the operation that matters
Compare the current design with the proposed one using the same application and dataset. Test a failure and recovery as well as ordinary traffic. Record the improvement, errors, stale reads, costs and limits.
Use the application test method and the database value framework to keep the decision comparable. For retrieval workloads, the AI database evaluation adds relevance and filtering checks. Keep a central design if it meets the requirement with less work; distribute data when the evidence supports it.